Learning plus Planning
Robots must learn from experience and data to be efficient in unmodeled, unknown, and previously unseen domains. There are many methods for learning implicit models of the world, which capture everything from a 3D reconstruction of a scene, quantifying the risk of collision, understanding task constraints from human demonstrations, and more. There are endless opportunities for integrating these models within existing algorithm frameworks or new neurosymbolic approaches to generalize planning capabilities to previously considered intractable problems.
2026
- NeHMO: Neural Hamilton-Jacobi Reachability Learning for Decentralized Safe Multi-Agent Motion PlanningIn IEEE/RSJ International Conference on Intelligent Robots and SystemsTo Appear
Safe multi-arm motion planning is a challenging problem in robotics due to its high dimensionality, coupled configuration space, and complex collision constraints. Centralized planners are capable of coordinating all arms but often face scalability limitations, restricting applicability in real-time settings. On the other hand, decentralized methods are scalable and recent deep learning-based approaches have shown promising results. However, these depend on accurate behavior prediction or coordination protocols and may fail when other arms act unpredictably. To address these challenges, we introduce a neural Hamilton-Jacobi Reachability (HJR) learning-based approach to approximate a safety value function that captures worst-case inter-arm safety constraints. We further develop a decentralized trajectory optimization framework that uses the learned HJR representation for real-time planning. The proposed method is scalable and data-efficient, generalizes across multi-manipulator systems, and outperforms state-of-the-art baselines on challenging multi-arm motion planning tasks.
@inproceedings{chen2026nehmo, author = {Chen, Qingyi and Kingston, Zachary and Qureshi, Ahmed H.}, booktitle = {IEEE/RSJ International Conference on Intelligent Robots and Systems}, note = {To Appear}, title = {{NeHMO}: Neural {Hamilton-Jacobi} Reachability Learning for Decentralized Safe Multi-Agent Motion Planning}, year = {2026} } - CDE: Concept-Driven Exploration for Reinforcement LearningIn IEEE/RSJ International Conference on Intelligent Robots and SystemsTo Appear
Intelligent exploration remains a critical challenge in reinforcement learning (RL), especially in visual control tasks. Unlike low-dimensional state-based RL, visual RL must extract task-relevant structure from raw pixels, making exploration inefficient. We propose Concept-Driven Exploration (CDE), which leverages a pre-trained vision-language model (VLM) to generate object-centric visual concepts from textual task descriptions as weak, potentially noisy supervisory signals. Rather than directly conditioning on these noisy signals, CDE trains a policy to reconstruct the concepts via an auxiliary objective, using reconstruction accuracy as an intrinsic reward to guide exploration toward task-relevant objects. Because the policy internalizes these concepts, VLM queries are only needed during training, reducing dependence on external models during deployment. Across five challenging simulated visual manipulation tasks, CDE achieves efficient, targeted exploration and remains robust to noisy VLM predictions. Finally, we demonstrate real-world transfer by deploying CDE on a Franka Research 3 arm, attaining an 80% success rate in a real-world manipulation task.
@inproceedings{mao2026cde, author = {Mao, Le and Liu, Andrew H. and Zabounidis, Renos and Niu, Yanan and Kingston, Zachary and Campbell, Joseph}, booktitle = {IEEE/RSJ International Conference on Intelligent Robots and Systems}, note = {To Appear}, title = {{CDE}: Concept-Driven Exploration for Reinforcement Learning}, year = {2026} } - Parallel Heuristic Search as Inference for Actor-Critic Reinforcement Learning ModelsIn IEEE International Conference on Robotics and AutomationTo Appear
Actor-Critic models are a class of model-free deep reinforcement learning (RL) algorithms that have demonstrated effectiveness across various robot learning tasks. While considerable research has focused on improving training stability and data sampling efficiency, most deployment strategies have remained relatively simplistic, typically relying on direct actor policy rollouts. In contrast, we propose PACHS (Parallel Actor-Critic Heuristic Search), an efficient parallel best-first search algorithm for inference that leverages both components of the actor-critic architecture: the actor network generates actions, while the critic network provides cost-to-go estimates to guide the search. Two levels of parallelism are employed within the search – actions and cost-to-go estimates are generated in batches by the actor and critic networks respectively, and graph expansion is distributed across multiple threads. We demonstrate the effectiveness of our approach in robotic manipulation tasks, including collision-free motion planning and contact-rich interactions such as non-prehensile pushing.
@inproceedings{yang2026pachs, author = {Yang, Hanlan and Mishani, Itamar and Pivetti, Luca and Kingston, Zachary and Likhachev, Maxim}, booktitle = {IEEE International Conference on Robotics and Automation}, note = {To Appear}, title = {Parallel Heuristic Search as Inference for Actor-Critic Reinforcement Learning Models}, year = {2026} } - One-shot View Planning and Online Optimization-based Replanning for Unknown Object ReconstructionJosé J. Patiño, Zachary Kingston, Victor Romero-Cano, Yu-Kun Lai, and Juan David HernándezIn IEEE International Conference on Robotics and AutomationTo Appear
Robotic inspection tasks often require constructing high-quality 3D models of objects from a minimal number of views. Traditional next-best view planning (NBVP) approaches incrementally select view poses but fail to account for global optimality of the inspection trajectory, thus leading to inefficient inspection paths. Recent one-shot view planning (OSVP) methods address this challenge by predicting informative view poses from an initial observation. While subsequent improvements on the pioneering OSVP approach attempt to improve prediction accuracy, they can still fail when faced with out of distribution(OoD) examples. With recent advances in generative modeling, OSVP methods can infer a plausible object shape from one observation and then derive the corresponding solution set of view poses. However, because the predicted shape may deviate from the true geometry, these methods can still generate infeasible views. To overcome these limitations, we propose a novel OSVP framework that leverages RGB-D data to generate geometric priors and incorporates online video-based reconstruction. Our method formulates viewpoint selection and path optimization, so that both the calculated poses and the connecting trajectories satisfy visibility constraints, maintain smoothness, and can be locally replanned to compensate for discrepancies between predicted and real object geometries. We validate our OSVP approach through simulation benchmarks against state-of-the-art OSVP techniques and demonstrate its effectiveness on a real Franka Emika manipulator.
@inproceedings{patino2026oneshot, author = {Pati\~no, Jos\'e J. and Kingston, Zachary and Romero-Cano, Victor and Lai, Yu-Kun and Hern\'andez, Juan David}, booktitle = {IEEE International Conference on Robotics and Automation}, note = {To Appear}, title = {One-shot View Planning and Online Optimization-based Replanning for Unknown Object Reconstruction}, year = {2026} } - SoRoParallel Simulation of Contact and Actuation for Soft Growing RobotsYitian Gao*, Lucas Chen*, Priyanka Bhovad, Sicheng Wang, Zachary Kingston, and Laura H. BlumenscheinSoft Robotics
Soft growing robots, commonly referred to as vine robots, have demonstrated remarkable ability to interact safely and robustly with unstructured and dynamic environments. It is therefore natural to exploit contact with the environment for planning and design optimization tasks. Previous research has focused on planning under contact for passively deforming robots with pre-formed bends. However, adding active steering to these soft growing robots is necessary for successful navigation in more complex environments. To this end, we develop a unified modeling framework that integrates vine robot growth, bending, actuation, and obstacle contact. We extend the beam moment model to include the effects of actuation on kinematics under growth and then use these models to develop a fast parallel simulation framework. We validate our model and simulator with real robot experiments. To showcase the capabilities of our framework, we apply our model in a design optimization task to find designs for vine robots navigating through cluttered environments, identifying designs that minimize the number of required actuators by exploiting environmental contacts. We show the robustness of the designs to environmental and manufacturing uncertainties. Finally, we fabricate an optimized design and successfully deploy it in an obstacle-rich environment.
@article{gaochen2025actsim, author = {Gao, Yitian and Chen, Lucas and Bhovad, Priyanka and Wang, Sicheng and Kingston, Zachary and Blumenschein, Laura H.}, doi = {10.1177/21695172261425906}, journal = {Soft Robotics}, title = {Parallel Simulation of Contact and Actuation for Soft Growing Robots}, year = {2026} } - Look as You Leap: Planning Simultaneous Motion and Perception for High-DoF RobotsQingxi Meng, Emiliano Flores, Carlos Quintero-Peña, Peizhu Qian, Zachary Kingston, Shannan K. Hamlin, Vaibhav Unhelkar, and Lydia E. KavrakiIEEE Transactions on Robotics
In this work, we address the problem of planning robot motions for a high-degree-of-freedom (DoF) robot that effectively achieves a given perception task while the robot and the perception target move in a dynamic environment. Achieving navigation and perception tasks simultaneously is challenging, as these objectives often impose conflicting requirements. Existing methods that compute motion under perception constraints fail to account for obstacles, are designed for low-DoF robots, or rely on simplified models of perception. Furthermore, in dynamic real-world environments, robots must replan and react quickly to changes and directly evaluating the quality of perception (e.g., object detection confidence) is often expensive or infeasible at runtime. This problem is especially important in human-centered environments such as homes and hospitals, where effective perception is essential for safe and reliable operation. To address these challenges, we propose a GPU-parallelized perception-score-guided probabilistic roadmap planner with a neural surrogate model (PS-PRM). The planner explicitly incorporates the estimated quality of a perception task into motion planning for high-DoF robots. Our method uses a learned model to approximate perception scores and leverages GPU parallelism to enable efficient online replanning in dynamic settings. We demonstrate that our planner, evaluated on high-DoF robots, outperforms baseline methods in both static and dynamic environments in both simulation and real-robot experiments.
@article{meng2026look, author = {Meng, Qingxi and Flores, Emiliano and Quintero-Peña, Carlos and Qian, Peizhu and Kingston, Zachary and Hamlin, Shannan K. and Unhelkar, Vaibhav and Kavraki, Lydia E.}, doi = {10.1109/TRO.2026.3731487}, journal = {IEEE Transactions on Robotics}, pages = {1--20}, title = {Look as You Leap: Planning Simultaneous Motion and Perception for High-{DoF} Robots}, year = {2026} } - arXivReVAMP: Vector-Accelerated Motion Planning for Kinematically-Constrained Systems via ReparameterizationUnder Review
Robots often must satisfy one or more constraints during motion planning for real-world tasks. When such constraints reduce the valid configuration space to a measure-zero subset, sampling based planning algorithms require modifications to draw feasible samples. For many common end-effector constraints, parameterizations built on inverse kinematics (IK) provide an alternate formulation where the constraints are satisfied by construction, allowing directly sampling the feasible set. Despite their elegant approach, parameterized planners have remained slower than vector-accelerated implementations of projection-based approaches, leaving their performance ceiling an open question. We explore a new axis of vectorization built upon reparameterizing the planning space through analytic IK. This approach addresses existing inefficiencies in vectorized projection-based planners and exposes new opportunities for parallelism within the planner. We show that the planner can synthesize plans in microseconds to milliseconds for high dimensional systems (up to 20 dimensions), with complex constraints, up to 10x faster than the current state-of-the-art. Furthermore, we demonstrate how such planning speeds open up avenues for restructuring sequential manipulation pipelines.
@misc{iyer2026revamp, archiveprefix = {arXiv}, author = {Iyer, Shrutheesh R. and Cohn, Thomas and Kingston, Zachary}, eprint = {2609.30213}, note = {Under Review}, primaryclass = {cs.RO}, title = {ReVAMP: Vector-Accelerated Motion Planning for Kinematically-Constrained Systems via Reparameterization}, year = {2026} } - arXivFaster Visuomotor Policy Learning on Action Manifolds via Riemannian MeanFlowUnder Review
Visuomotor policies learn a direct map from raw sensory observations to robot action sequences. Policies based on Diffusion and Flow Matching capture the multimodal distribution over action sequences in an end-to-end manner. This expressivity comes at the cost of multi-step numerical integration of the learned vector field for action generation, which can be expensive and time-consuming, impeding fast control rates required in robotics applications. Furthermore, robot action sequences are usually defined on a smooth, differentiable manifold, requiring that the learned policy respects the intrinsic geometry of the robot’s action space. Here, we present Riemannian MeanFlow Policy (RMFP), which learns the conditioned flow map of the probability path on the robot action manifold. Our formulation employs a flow map consistency objective grounded in the data by a Riemannian Conditional Flow Matching anchor. The flow map consistency condition is stable to train and constrains the learned model to finite-time transport, which yields on-manifold action sequence generation with as few as one network function evaluation. We present results on the spherical LASA and Push-T benchmarks, on the Tool Hang and Transport tasks of the Robomimic suite, and on the Franka Kitchen task with manifold-constrained action generation, and demonstrate that RMFP attains performance competitive with prior work at a lower sampling cost. We also employ RMFP on a real-world robotic manipulation task to demonstrate fast action generation under imperfect sensor measurements in the physical world.
@misc{bukhari2026rmfp, archiveprefix = {arXiv}, author = {Bukhari, S. Talha and Garrett, Austin and Wei, Yi and Ni, Ruiqi and Kingston, Zachary and Bera, Aniket}, eprint = {2609.30127}, note = {Under Review}, primaryclass = {cs.RO}, title = {Faster Visuomotor Policy Learning on Action Manifolds via {R}iemannian {MeanFlow}}, year = {2026} } - arXiv
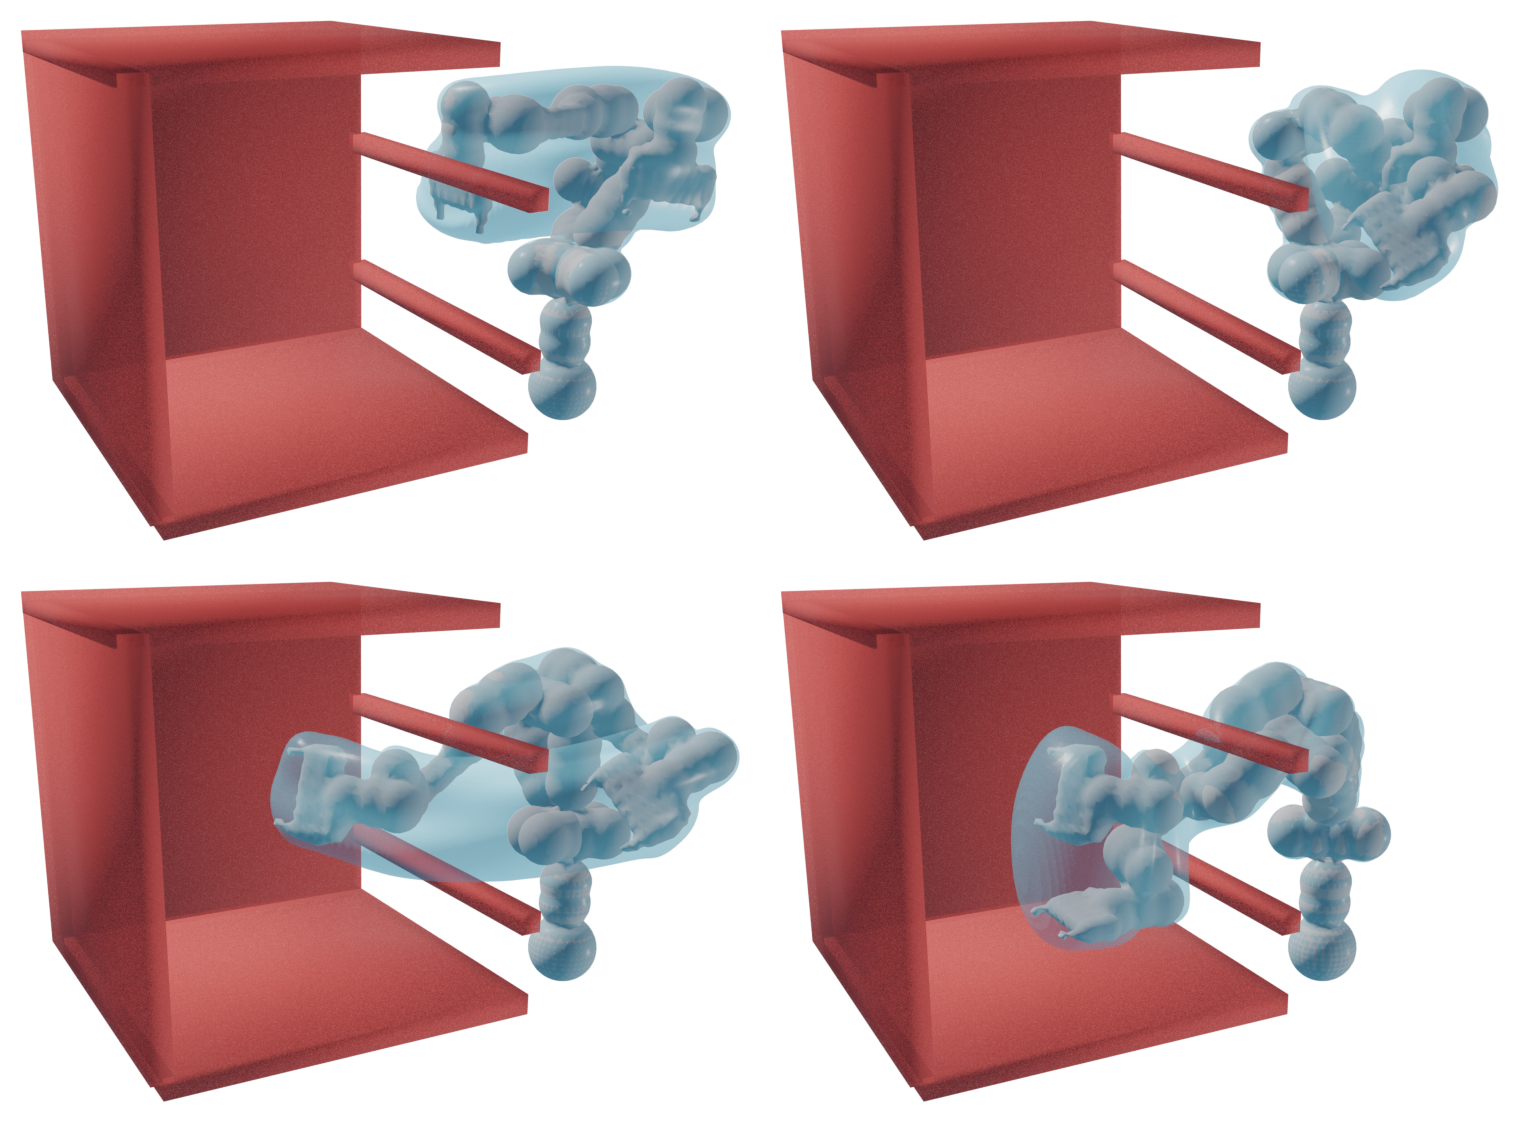 Stochastic Neural Signed Swept Volume for Real-time Chance-Constrained Trajectory OptimizationUnder Review
Collision-free motion planning requires reliable collision models from sensed environments and validation of states along a continuous trajectory. To make this tractable, most planners check for collision at discrete states along continuous trajectories against a single determinized model of the environment, introducing a trade-off between safety and computational efficiency. While continuous collision checking approaches that approximate the swept volume of the robot exist, they are computationally expensive or overly conservative. Data-driven approaches can learn the swept volume; however, these neural models are susceptible to approximation errors and are therefore often limited to serving as coarse filters for downstream collision checkers. In this work, we propose to learn a signed distance function of the swept volume as a probabilistic field, enabling quantification of epistemic uncertainty, incorporation of perception noise, and eventual integration into a chance-constrained trajectory optimization framework. We demonstrate our approach on challenging high-dimensional manipulation problems with significant sensor noise, both in simulation and on real hardware.
@misc{chen2026sweptvolume, archiveprefix = {arXiv}, author = {Chen, Qingyi and Zhang, Kevin and Chen, Lucas and Kingston, Zachary}, eprint = {2609.21211}, note = {Under Review}, primaryclass = {cs.RO}, title = {Stochastic Neural Signed Swept Volume for Real-time Chance-Constrained Trajectory Optimization}, year = {2026} } - arXivSafe Real-Time Policy Steering via Noise-Space Trajectory Optimization for One-Step Generative PoliciesUnder Review
Generative robot policies can represent diverse, multimodal behaviors, but adapting pretrained policies to deployment-time constraints such as collision avoidance and orientation maintenance remains challenging. Existing inference-time steering methods typically apply gradient guidance through iterative diffusion or flow processes, which can be computationally expensive for real-time control. We propose INSPO, which formulates inference-time steering of one-step generative policies as trajectory optimization in the policy’s input noise space. By optimizing the input noise while evaluating constraints on the induced state trajectory, INSPO searches the policy-induced behavior space without directly modifying generated actions. The optimization includes a regularization term that encourages solutions to remain consistent with the policy’s input distribution and is solved online using population-based particle optimization. We evaluate INSPO on state- and image-based task-specific policies and generalist vision-language-action policies across Push-T, Can pick-and-place, and LIBERO-Spatial. INSPO improves task success and constraint satisfaction over best-of-N sampling and action projection, while comparing favorably with gradient-guided generation at lower runtime.
@misc{chen2026inspo, archiveprefix = {arXiv}, author = {Chen, Qingyi and Ruan, Joseph and Kingston, Zachary}, eprint = {2609.21220}, note = {Under Review}, primaryclass = {cs.RO}, title = {Safe Real-Time Policy Steering via Noise-Space Trajectory Optimization for One-Step Generative Policies}, year = {2026} } - arXiv
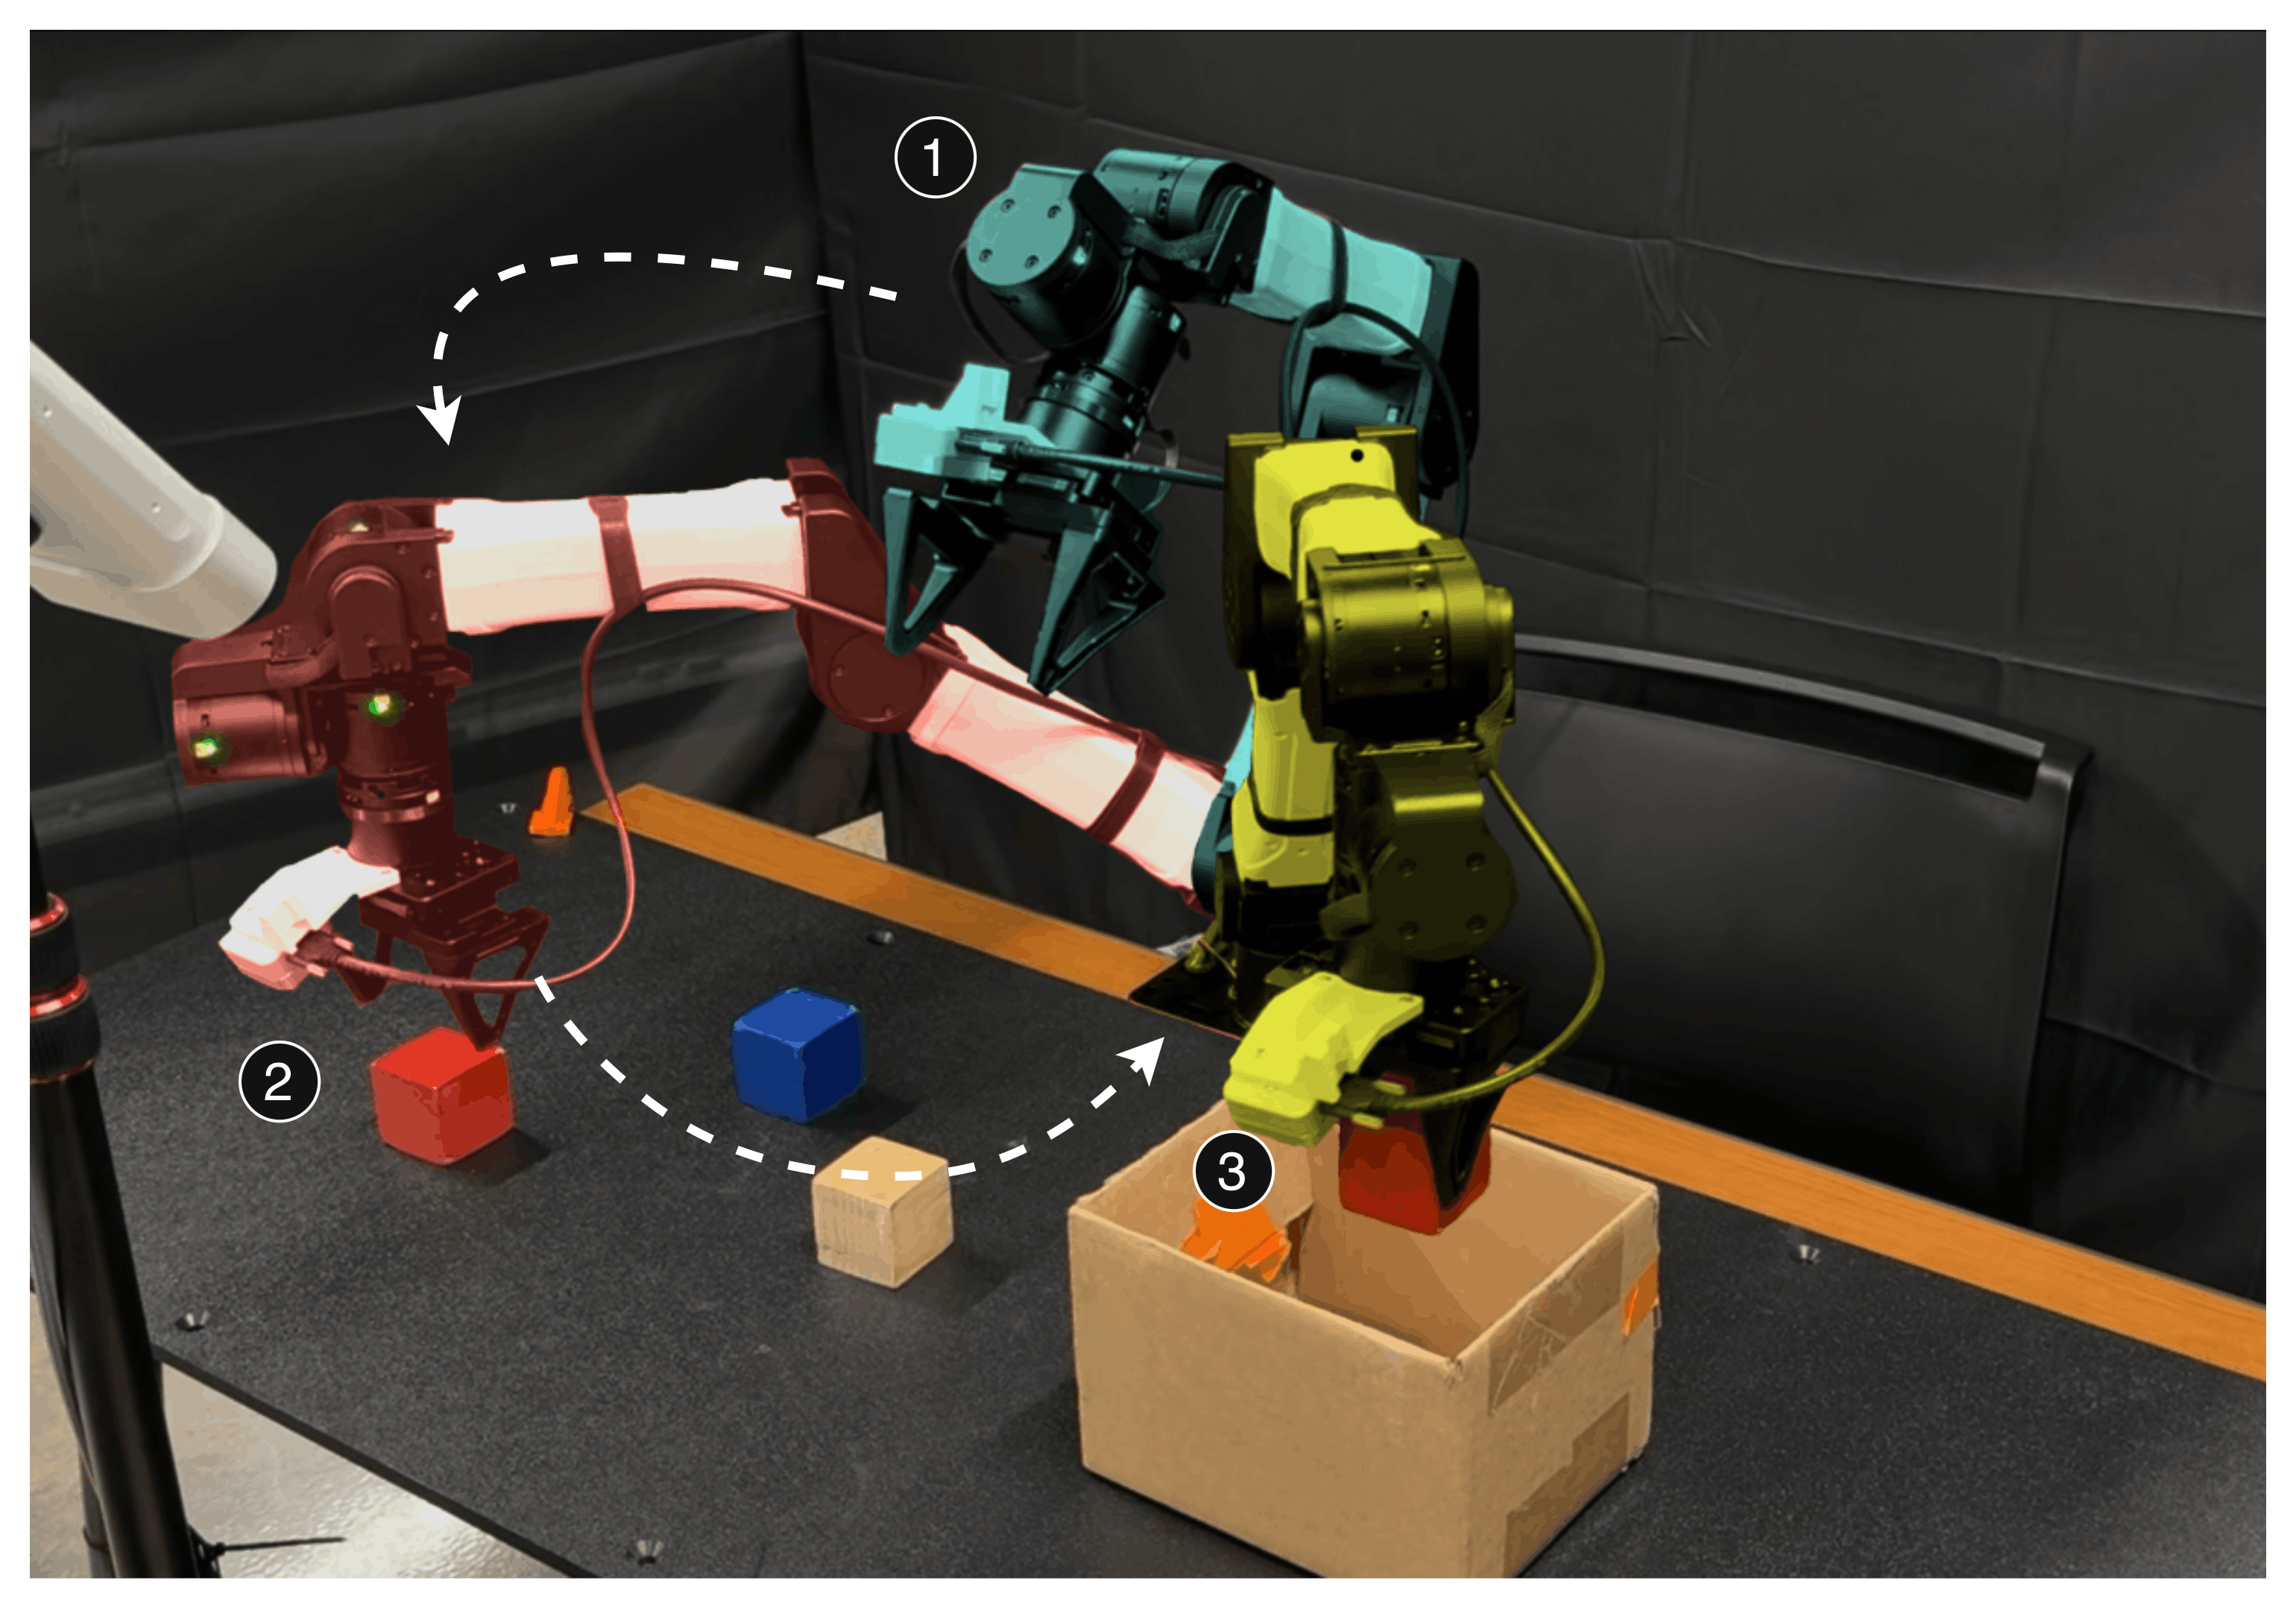 SkipVLA: Skipping VLA Steps with Classical Planning for Fast Robot ManipulationUnder Review
Vision-Language-Action (VLA) models are a class of generalist robot policies that map camera images and language instructions directly to robot actions. While promising, these models remain slow at test time, particularly for long-horizon tasks that require many queries to the policy. Recent efforts reduce VLA latency by distilling smaller models, overlapping asynchronous action chunks, or pairing the VLA with a fast low-level policy, but still run a learned policy for the entire task. In contrast to VLA, classical motion planners quickly find collision-free motions, but require an explicit goal and have no semantic understanding of the task. In this work, we present SkipVLA, a hybrid policy that combines a pretrained VLA with a classical motion planner, using the planner for free-space motion and querying the VLA only for contact-rich skills such as grasping and placing. SkipVLA reuses the frozen vision-language backbone of the VLA to predict a target pose for each planned motion, and learns this predictor without additional demonstrations introduced into the system by using what was already learnt by the large VLA. We evaluate SkipVLA with three VLAs on 13 LIBERO tasks in simulation and three pick-and-place tasks on a physical 6-DoF YAM arm, demonstrating up to 2.5x faster task completion and significantly lower energy consumption while achieving the same task success rate.
@misc{agrawal2026skipvla, archiveprefix = {arXiv}, author = {Agrawal, Kaivalya and Rahman, Md Ashiqur and Yeh, Raymond A. and Kingston, Zachary}, eprint = {2609.20648}, note = {Under Review}, primaryclass = {cs.RO}, title = {SkipVLA: Skipping VLA Steps with Classical Planning for Fast Robot Manipulation}, year = {2026} } - arXiv
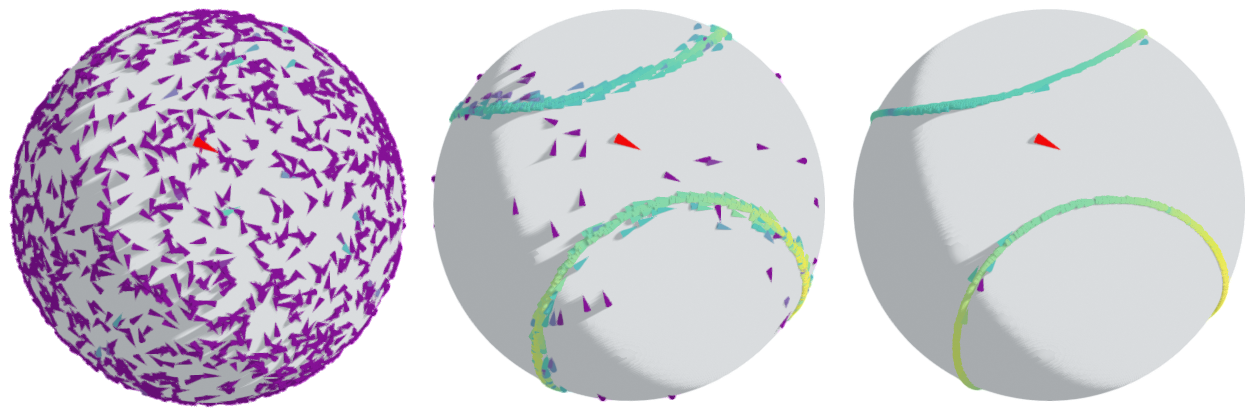 Fast Generative Grasping via Lie Group-Constrained MeanFlowUnder Review
Grasp synthesis is a core task in robotic manipulation, for which the solution typically forms a multimodal distribution rather than a point estimate. Generative robotic grasping aims to learn this distribution with deep generative models such as diffusion and flow-based approaches. The iterative nature of such generative models makes them flexible and generalizable; however, multi-step sampling impedes the time-critical operation required in robotics. We devise an approach to fast generative grasping based on MeanFlow on the product Lie group SO(3) x R^3. The training objective couples a purely algebraic semigroup consistency condition with Riemannian Conditional Flow Matching on the product Lie group that anchors the average velocity to the data distribution. The resulting Lie Group-constrained MeanFlow formulation samples reliable grasps in at most 5 network evaluations, matching the grasp generation performance of state-of-the-art diffusion and flow-based models on the ACRONYM dataset at millisecond-scale inference latency (up to 39 times speed-up). We further demonstrate that the approach directly translates to real-world robotic grasping without additional training or domain adaptation, exhibiting robust grasp synthesis under observation noise.
@misc{bukhari2026meanflow, archiveprefix = {arXiv}, author = {Bukhari, S. Talha and Wei, Yi and Ni, Ruiqi and Kingston, Zachary and Bera, Aniket}, eprint = {2608.26076}, note = {Under Review}, primaryclass = {cs.RO}, title = {Fast Generative Grasping via {L}ie Group-Constrained {MeanFlow}}, year = {2026} } - arXivPLanAR: Planning-Language-Grounded Agentic Reasoning for Robot ManipulationPengyuan Guo, Zhonghao Mai, Zhengtong Xu, Kaidi Zhang, Heng Zhang, Zichen Miao, Arash Ajoudani, Zachary Kingston, Qiang Qiu, and Yu SheUnder Review
Recent advances in vision-language models (VLMs) have enabled increasing progress in real-world robot manipulation. However, long-horizon manipulation in unstructured environments requires VLMs to reason about changing scene states, action constraints, and execution outcomes, which remains difficult with natural language reasoning alone. We present PLanAR, a planning-language-grounded robot agent framework for open-vocabulary, long-horizon manipulation. PLanAR uses a planning-language interface to define the VLM reasoning space: object predicates represent scene states, action schemas specify robot skills with preconditions and effects, and symbolic plans provide executable intermediate representations. This interface enables stepwise verification: after each action, PLanAR uses onboard observations to check whether the expected symbolic effects have been achieved, allowing the VLM-based agent to update task states, detect failures, and replan when execution deviates from expectation. Across robot embodiments, VLM backends, and tasks including stacking, crossword solving, and long-horizon kitchen workflows, PLanAR demonstrates strong real-world capability while revealing key limitations of current VLMs in embodied reasoning.
@misc{guo2026planar,
  archiveprefix = {arXiv},
  author = {Guo, Pengyuan and Mai, Zhonghao and Xu, Zhengtong and Zhang, Kaidi and Zhang, Heng and Miao, Zichen and Ajoudani, Arash and Kingston, Zachary and Qiu, Qiang and She, Yu},
  eprint = {2602.01662},
  note = {Under Review},
  primaryclass = {cs.RO},
  title = {{PLanAR}: Planning-Language-Grounded Agentic Reasoning for Robot Manipulation},
  year = {2026}
}


2025
- Variational Shape Inference for Grasp Diffusion on SE(3)IEEE Robotics and Automation Letters
Grasp synthesis is a fundamental task in robotic manipulation which usually has multiple feasible solutions. Multimodal grasp synthesis seeks to generate diverse sets of stable grasps conditioned on object geometry, making the robust learning of geometric features crucial for success. To address this challenge, we propose a framework for learning multimodal grasp distributions that leverages variational shape inference to enhance robustness against shape noise and measurement sparsity. Our approach first trains a variational autoencoder for shape inference using implicit neural representations, and then uses these learned geometric features to guide a diffusion model for grasp synthesis on the SE(3) manifold. Additionally, we introduce a test-time grasp optimization technique that can be integrated as a plugin to further enhance grasping performance. Experimental results demonstrate that our shape inference for grasp synthesis formulation outperforms state-of-the-art multimodal grasp synthesis methods on the ACRONYM dataset by 6.3%, while demonstrating robustness to deterioration in point cloud density compared to other approaches. Furthermore, our trained model achieves zero-shot transfer to real-world manipulation of household objects, generating 34% more successful grasps than baselines despite measurement noise and point cloud calibration errors.
@article{bukhari2025graspdiff, author = {Bukhari, S. Talha and Agrawal, Kaivalya and Kingston, Zachary and Bera, Aniket}, doi = {10.1109/LRA.2025.3645521}, journal = {IEEE Robotics and Automation Letters}, title = {Variational Shape Inference for Grasp Diffusion on SE(3)}, year = {2025} } - arXivUsing VLM Reasoning to Constrain Task and Motion PlanningUnder Review
In task and motion planning, high-level task planning is done over an abstraction of the world to enable efficient search in long-horizon robotics problems. However, the feasibility of these task-level plans relies on the downward refinability of the abstraction into continuous motion. When a domain’s refinability is poor, task-level plans that appear valid may ultimately fail during motion planning, requiring replanning and resulting in slower overall performance. Prior works mitigate this by encoding refinement issues as constraints to prune infeasible task plans. However, these approaches only add constraints upon refinement failure, expending significant search effort on infeasible branches. We propose VIZ-COAST, a method of leveraging the common-sense spatial reasoning of large pretrained Vision-Language Models to identify issues with downward refinement a priori, bypassing the need to fix these failures during planning. Experiments on two challenging TAMP domains show that our approach is able to extract plausible constraints from images and domain descriptions, drastically reducing planning times and, in some cases, eliminating downward refinement failures altogether, generalizing to a diverse range of instances from the broader domain.
@misc{yan2025vizcoast, archiveprefix = {arXiv}, author = {Yan, Muyang and Mengdibayev, Miras and Floros, Ardon and Guo, Weihang and Kavraki, Lydia E. and Kingston, Zachary}, eprint = {2510.25548}, note = {Under Review}, primaryclass = {cs.RO}, title = {Using {VLM} Reasoning to Constrain Task and Motion Planning}, year = {2025} } - Workshop
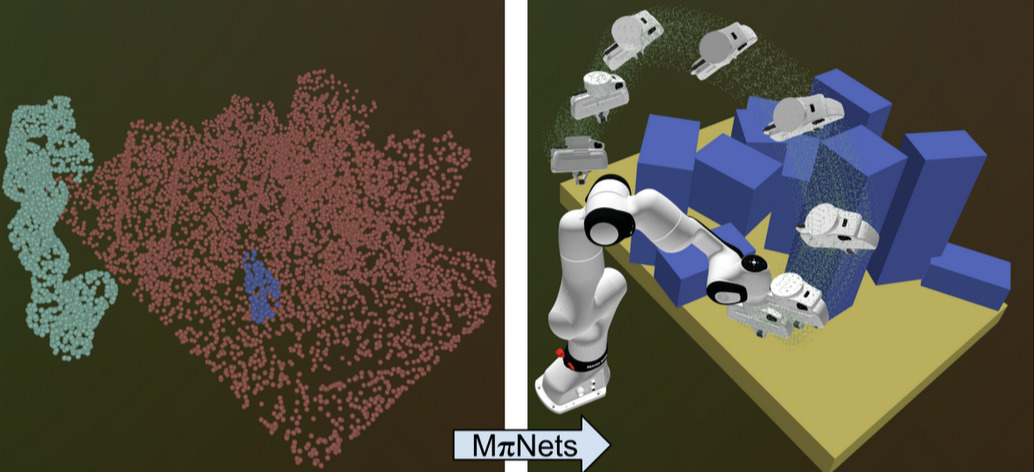 Faster Behavior Cloning with Hardware-Accelerated Motion Planning
@misc{buynitsky2025wksp,
  author = {Buynitsky, Alexiy and Kingston, Zachary},
  booktitle = {IEEE ICRA 2025 Workshop---RoboARCH: Robotics Acceleration with Computing Hardware and Systems},
  title = {Faster Behavior Cloning with Hardware-Accelerated Motion Planning},
  year = {2025}
}

2024
- AbstractPerception-aware Planning for Robotics: Challenges and Opportunities
In this work, we argue that new methods are needed to generate robot motion for navigation or manipulation while effectively achieving perception goals. We support our argument by conducting experiments with a simulated robot that must accomplish a primary task, such as manipulation or navigation, while concurrently monitoring an object in the environment. Our preliminary study demonstrates that a decoupled approach fails to achieve high success in either action-focused motion generation or perception goals, motivating further developments of approaches that holistically consider both goals.
@misc{meng2024icra40, author = {Meng, Qingxi and Quintero-Peña, Carlos and Kingston, Zachary and Unhelkar, Vaibhav and Kavraki, Lydia E.}, booktitle = {40th Anniversary of the IEEE Conference on Robotics and Automation (ICRA@40)}, title = {Perception-aware Planning for Robotics: Challenges and Opportunities}, year = {2024} } - Stochastic Implicit Neural Signed Distance Functions for Safe Motion Planning under Sensing UncertaintyIn IEEE International Conference on Robotics and Automation
Motion planning under sensing uncertainty is critical for robots in unstructured environments to guarantee safety for both the robot and any nearby humans. Most work on planning under uncertainty does not scale to high-dimensional robots such as manipulators, assumes simplified geometry of the robot or environment, or requires per-object knowledge of noise. Instead, we propose a method that directly models sensor-specific aleatoric uncertainty to find safe motions for high-dimensional systems in complex environments, without exact knowledge of environment geometry. We combine a novel implicit neural model of stochastic signed distance functions with a hierarchical optimization-based motion planner to plan low-risk motions without sacrificing path quality. Our method also explicitly bounds the risk of the path, offering trustworthiness. We empirically validate that our method produces safe motions and accurate risk bounds and is safer than baseline approaches.
@inproceedings{quintero2024impdist,
  author = {Quintero-Peña, Carlos and Thomason, Wil and Kingston, Zachary and Kyrillidis, Anastasios and Kavraki, Lydia E.},
  booktitle = {IEEE International Conference on Robotics and Automation},
  doi = {10.1109/ICRA57147.2024.10610773},
  pages = {2360--2367},
  title = {Stochastic Implicit Neural Signed Distance Functions for Safe Motion Planning under Sensing Uncertainty},
  year = {2024}
}

2023
- Object Reconfiguration with Simulation-Derived Feasible ActionsIn IEEE International Conference on Robotics and Automation
3D object reconfiguration encompasses common robot manipulation tasks in which a set of objects must be moved through a series of physically feasible state changes into a desired final configuration. Object reconfiguration is challenging to solve in general, as it requires efficient reasoning about environment physics that determine action validity. This information is typically manually encoded in an explicit transition system. Constructing these explicit encodings is tedious and error-prone, and is often a bottleneck for planner use. In this work, we explore embedding a physics simulator within a motion planner to implicitly discover and specify the valid actions from any state, removing the need for manual specification of action semantics. Our experiments demonstrate that the resulting simulation-based planner can effectively produce physically valid rearrangement trajectories for a range of 3D object reconfiguration problems without requiring more than an environment description and start and goal arrangements.
@inproceedings{lee2023physics,
  author = {Lee, Yiyuan and Thomason, Wil and Kingston, Zachary and Kavraki, Lydia E.},
  booktitle = {IEEE International Conference on Robotics and Automation},
  doi = {10.1109/ICRA48891.2023.10160377},
  number = {},
  pages = {8104--8111},
  title = {Object Reconfiguration with Simulation-Derived Feasible Actions},
  volume = {},
  year = {2023}
}

2021
- Learning Sampling Distributions Using Local 3D Workspace Decompositions for Motion Planning in High DimensionsConstantinos Chamzas, Zachary Kingston, Carlos Quintero-Peña, Anshumali Shrivastava, and Lydia E. KavrakiIn IEEE International Conference on Robotics and Automation
Nominated for Best Paper in Cognitive Robotics.
Earlier work has shown that reusing experience from prior motion planning problems can improve the efficiency of similar, future motion planning queries. However, for robots with many degrees-of-freedom, these methods exhibit poor generalization across different environments and often require large datasets that are impractical to gather. We present SPARK and FLAME, two experience-based frameworks for sampling- based planning applicable to complex manipulators in 3D environments. Both combine samplers associated with features from a workspace decomposition into a global biased sampling distribution. SPARK decomposes the environment based on exact geometry while FLAME is more general, and uses an octree-based decomposition obtained from sensor data. We demonstrate the effectiveness of SPARK and FLAME on a real and simulated Fetch robot tasked with challenging pick-and-place manipulation problems. Our approaches can be trained incrementally and significantly improve performance with only a handful of examples, generalizing better over diverse tasks and environments as compared to prior approaches.
@inproceedings{chamzas2021flame,
  author = {Chamzas, Constantinos and Kingston, Zachary and Quintero-Peña, Carlos and Shrivastava, Anshumali and Kavraki, Lydia E.},
  booktitle = {IEEE International Conference on Robotics and Automation},
  doi = {10.1109/ICRA48506.2021.9561104},
  pages = {1283--1289},
  title = {Learning Sampling Distributions Using Local 3D Workspace Decompositions for Motion Planning in High Dimensions},
  year = {2021}
}
